
Connect. Secure. Manage.
Industrial Network Resilience
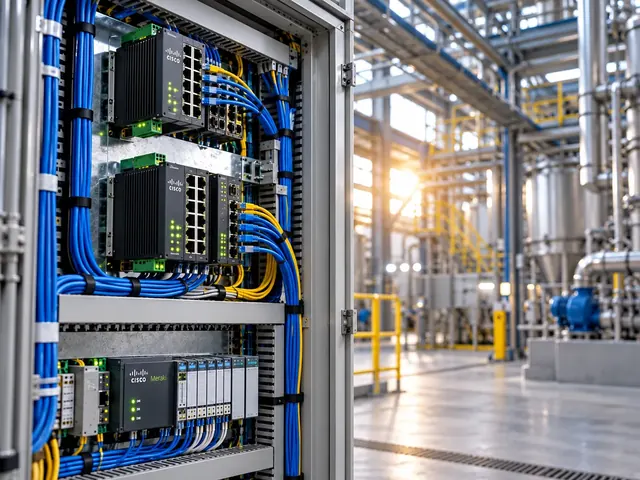
Review Cisco industrial network recovery paths and failure domains, with change windows and validation agreed with the operational technology owner.
Devices supported
across the UK
Client locations
supported
Traffic handled
at peak time
Average
response time
Average response is not a resolution time or a contractual guarantee. Support scope and response commitments are agreed for each engagement.
Industrial network resilience asks a direct question: can the process keep working when a link, device or power source fails? Extra switches alone do not answer it. We review Cisco networks against agreed faults and recovery needs. Tests and changes are planned with the operational owner before the live process is put at risk.
Cisco-focused engineering
Design around the platform, traffic and failure behaviour you actually operate.
Change with evidence
Use pre-checks, acceptance criteria and a documented route back.
Operational handover
Keep the configuration, diagrams and responsibilities understandable after delivery.
Define the interruption the process can tolerate
We ask which communications are critical, how quickly a failure must be detected and what the app does while network access is unavailable. Some systems recover automatically; others require operator intervention or a controlled restart. The network recovery aim needs to be meaningful in that operational context.
A vendor’s protocol convergence figure does not prove end-to-end recovery for the customer’s equipment. We separate link detection, network reconvergence, session recovery and process restoration. This helps the business decide whether the proposed topology meets its needs or whether endpoint, app or operational changes are also required.

Standards & partnerships
Confidence in the team behind your network.
 Cisco Partner
 Cisco Meraki
 Cyber Essentials
 Cyber Essentials Plus
MCI Network Services is operated by Proxar Ltd. Certifications apply to the certified legal entity and the scope of its certificates. View accreditation information
Identify common points of failure
We review switch hardware, uplinks, cabinet power, cable routes and the systems needed to manage the network. Two routes drawn separately can still share a duct, building entry or power source. Two devices can also share a software setup error or an upstream service that defeats the intended independence.
The review follows the traffic from source to destination, including the physical endpoint connection. A controller with one network port and one cable remains dependent on that connection unless the wider system offers another supported arrangement. We state those limitations clearly rather than describing a redundant backbone as protection for every attached device.

A useful starting point
Not sure where to start?
Bring the requirement. We will help you define the engineering work.
Select the appropriate recovery mechanism
Industrial networks may use supported ring, routed or specialised redundancy technologies. The correct choice depends on the equipment, protocol needs and operating constraints. We check support across the complete topology instead of assuming that devices from different product families implement compatible behaviour.
Technologies such as PRP or HSR have specific architecture and endpoint needs. They should not be reduced to a promise of zero interruption for an arbitrary network. We examine how devices connect, where duplicate traffic is handled and what failure conditions the design is intended to tolerate. Ordinary spanning-tree or routing mechanisms may be more appropriate in other parts of the estate.

Different environments. The same care.
Built around the work
your network supports.
Finance, banking and the wider private sector. We start with the systems and people that depend on your connections.
Finance & banking
Market-data paths, routing and provider coordination on clients’ behalf.
Financial-market services ↗Offices & multi-site teams
Reliable access between people, workplaces and business applications.
Office network design ↗Data centres & cloud
Network boundaries, workload connections and operational ownership.
Data centre networks ↗Check capacity in the failed state
A backup path must carry the traffic that moves onto it. We review link usage, multicast replication, oversubscription and the demand associated with start-up or recovery. A network can reconverge correctly and still provide an unusable service because the remaining path is congested.
The assessment also considers monitoring traffic and engineering access during an incident. Diagnostic activity should not consume the headroom needed by operational services. Where traffic prioritisation is proposed, its classification and effect must be tested against actual apps rather than inferred from a generic quality-of-service template.

Plan failure tests with operations
We agree which faults can be simulated safely and which require a shutdown or representative test setup. Disconnecting a link or restarting a switch can have consequences beyond the network team. Written authority, an operational contact and a recovery procedure are prerequisites for disruptive testing.
Each test has a defined expected outcome and a stop condition. We record network state, app observations and the steps needed to restore normal operation. A test that cannot be performed is recorded as an evidence gap or an accepted assumption, not quietly counted as passed.

Test restoration as well as failure
Returning a failed path to service can trigger another topology change or expose inconsistent setup. We examine the recovery sequence, preferred-path behaviour and the effect of devices returning with stale or incomplete state. Operations should know whether restoration is automatic or needs a controlled intervention.
Replacement procedures matter too. Spare equipment, supported software, backups of the settings and physical access determine how quickly a degraded network can regain resilience. A design that survives the first fault but remains exposed for weeks because no compatible spare exists may not meet the customer’s operating expectations.

Keep resilience visible during normal operation
Monitoring should distinguish a total outage from the loss of a redundant component while production still works. The latter can be easy to overlook until a second fault causes disruption. We set out useful alarms, escalation ownership and periodic checks of the components that provide the alternative path.
MCI can review resilience as a standalone assessment or as part of Cisco industrial Ethernet design. The deliverable is a set of documented failure domains, supported recovery arrangements, observed test results and practical recommendations, with the customer’s operational and safety duties kept clear.
Talk to a specialist
What does your network need next?
Tell us what you are planning, changing or trying to improve. We will help define a practical next step and the engineering scope.
+44 203 196 6566Choose option 1
sales@proxar.co.ukUK-wide service.
Most of our engineers are based in Kent, with a focus on London, Sussex, Essex and Berkshire.
Existing customers should use their agreed support and escalation channels. This form is for service enquiries, not a monitored emergency ticket.
Tell us what you need.
A short outline is enough. Please do not include passwords or sensitive network details.
Thank you. Your enquiry has been submitted.
Please check your name, email and message, then try again.
Your form session expired. Please try again.
Please wait a minute before sending another enquiry.
We could not submit your enquiry. Please call or email us instead.